
Robot Arms
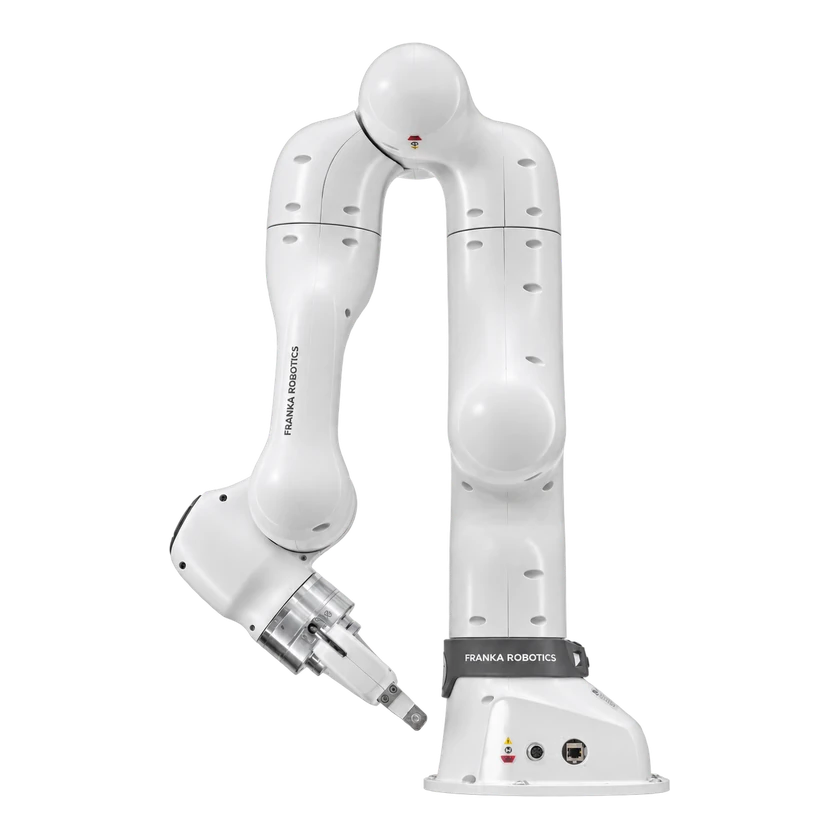
Franka Research 3
Lift, See, Act (LSA) ↗Real-robot experiment
The authors evaluated LSA on a Franka Research 3 with a parallel gripper and RealSense D435i.
Version scope and roles for these associations await verification.
Established by researchers at South China University of Technology, Lift, See, Act pretrains visual representations for robot manipulation from human video. It aligns intermediate features with two 3D teacher models, uses depth reconstruction and hand-region guidance, and learns to predict future 3D wrist motion. The authors evaluated the learned encoder in simulation and on a Franka Research 3 arm.
Robot models: 1 · Version relationships: 1
Experiments do not imply factory configuration. Evidence applies only to the named model version.
Robot Arms
The authors evaluated LSA on a Franka Research 3 with a parallel gripper and RealSense D435i.
Paper available
Author order: Original order
LSA pretraining method, simulation and real-robot experiments
Title not provided
LSA authors · Research paper
Published: 2026-11-16 · Accessed: 2026-11-21
Title not provided
LSA authors · Official website
Publication date unknown · Accessed: 2026-11-21
Title not provided
Apple · Code repository
Publication date unknown · Accessed: 2026-11-21
Title not provided
Meta FAIR · Model card
Publication date unknown · Accessed: 2026-11-21
Title not provided
LSA authors · Code repository
Publication date unknown · Accessed: 2026-11-21